The four main modes
Each mode trades character range for density. Numeric mode only handles digits but packs three of them into 10 bits, while byte mode handles any byte but spends 8 bits on each.
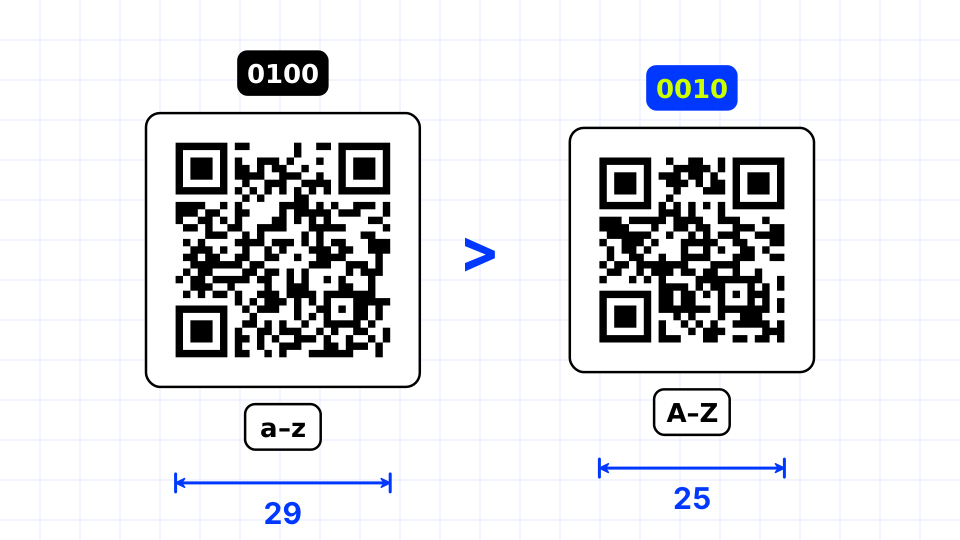
Alphanumeric mode covers a 45-character set: the digits 0–9, the uppercase letters A–Z, the space and the symbols $ % * + - . / and colon. Lowercase letters are not in the set, which is why an all-uppercase URL can make a smaller code than the same URL in lowercase.
- Numeric: digits 0–9, 10 bits per 3 digits
- Alphanumeric: 45 characters, 11 bits per 2 characters
- Byte: any 8-bit value, 8 bits per byte
- Kanji: Shift JIS double-byte characters, 13 bits each
Mode indicators and segments
Each run of data starts with a 4-bit mode indicator and a character count, whose length depends on the mode and the version. A code can contain several such segments, for example numeric for a long run of digits and byte for the rest, which can make the result smaller.
Other 4-bit indicators signal features rather than character sets: ECI for declaring a character encoding, structured append for splitting data across codes, and FNC1 for GS1 and other industry data formats. A terminator of four zero bits ends the data.
- Numeric 0001, alphanumeric 0010, byte 0100, kanji 1000
- ECI 0111, structured append 0011
- FNC1 first position 0101, second position 1001
- Terminator 0000
Byte mode and character sets
The standard’s default interpretation of byte mode is ISO-8859-1 (Latin-1), but most generators today write UTF-8 so that accented letters, other scripts and emoji survive. Readers usually detect UTF-8 by inspecting the bytes.
Where the character set must be unambiguous, an ECI header can declare it explicitly. Without one, a reader may occasionally guess wrong and show garbled characters.